TeamITServe

AI Governance

The Chatbot Told a Customer Something the Company Never Said. Guess Who Pays

In February 2024, a Canadian tribunal handed down a ruling that should be required reading in every boardroom deploying AI. A man named Jake Moffatt was booking a flight with Air Canada after his grandmother passed away. He asked the airline’s chatbot about bereavement fares. The bot told him he could book now at full price and apply for a bereavement discount retroactively within 90 days. That policy did not exist. Air Canada’s actual bereavement policy required the discount request before travel, not after. The chatbot invented a rule on the spot, said it with total confidence, and Moffatt believed it — because why wouldn’t he. When he filed for the refund the bot promised, Air Canada refused. Their argument in the tribunal was almost unbelievable: the chatbot is a separate legal entity responsible for its own words. The tribunal did not buy it. The ruling was blunt — a company is responsible for all the information on its website, whether it comes from a static page or a chatbot. Air Canada paid. Why This Case Changed the Conversation This was not a huge financial loss for Air Canada. A few hundred dollars. But the precedent it set is what actually matters, and it is rippling through legal and compliance departments right now. The ruling establishes something simple and uncomfortable: your AI speaking to a customer is legally the same as your company speaking to a customer. There is no separation. There is no “the bot said it, not us.” If your AI tells a customer something, your company told them that thing. For any business running a customer-facing AI tool — and in 2026 that is most businesses — these changes how you have to think about deployment. This Is Already Bigger Than One Airline Air Canada is the case everyone cites because it went to a tribunal and got documented. But it is far from an isolated incident. A car dealership in California had a customer negotiate their chatbot down to selling a vehicle for one dollar. The bot, trying to be agreeable, agreed to the price. The dealership had to publicly clarify the deal was not honoured, but it became a viral embarrassment that spread faster than any of their actual marketing. A major retailer’s AI shopping assistant confidently recommended products that did not exist in their catalogue, describing features and pricing it invented entirely, based on patterns from similar products. Customers who tried to order those items got confused and frustrated, and the support team had no idea why until someone traced it back to the bot’s chat logs. A telecom company’s support AI told a customer their contract could be cancelled without a fee under conditions that were not actually in the customer’s plan. The customer cancelled based on that information. When the fee showed up on their final bill, the company had to decide whether to honour what the AI said or fight it — and increasingly, companies are finding they do not have a strong legal position to fight it. Why This Keeps Happening Large language models are not databases. They do not retrieve facts from a fixed lookup table and return them precisely. They generate the most statistically plausible response to what they were asked, based on patterns learned during training. Most of the time this produces accurate, helpful answers. Sometimes it produces a completely fabricated policy stated with the same confidence as a real one. This is what the industry calls hallucination, and it is a known, unsolved characteristic of how these systems work — not a bug that gets patched away, but a fundamental behaviour that needs to be managed rather than eliminated. The problem is that most customer-facing AI deployments were built to sound confident and helpful. Nobody trained the bot to say “I am not certain, let me check with a human” often enough, because that feels like a worse customer experience in the moment. It is a much better outcome than confidently inventing a refund policy that costs the company money and credibility. What a Defensible AI Customer Framework Actually Looks Like The companies protecting themselves properly are building a few things into every customer-facing AI deployment. Clear scope boundaries. The AI is explicitly restricted from making statements about policy areas that carry financial or legal weight — refunds, contract terms, legal rights — unless those statements are pulled directly from a verified, current policy document rather than generated freely. Confidence-based escalation. When the AI is dealing with a query that touches money, legal terms, or anything outside clearly defined territory, it should default to connecting the customer with a human rather than guessing. The businesses handling this well have accepted that occasional friction is far cheaper than occasional false promises. Retrievable source citation. Instead of letting the AI generate an answer from general knowledge, well-built systems retrieve the actual current policy document and quote from it directly. This dramatically reduces hallucination because the AI is reading a real answer rather than inventing one. Logged and auditable conversations. Every customer-facing AI interaction should be logged and reviewable, so if something goes wrong, the company can see exactly what was said, why, and fix the underlying issue quickly rather than discovering it months later through a complaint or a tribunal filing. Human review of edge cases. A regular sample of AI conversations, especially any that touch policy, pricing, or commitments, should be reviewed by a person. Not every conversation. Enough to catch patterns before they become expensive. The Bottom Line The uncomfortable truth for any business deploying AI at the customer-facing edge is this: your AI is not a separate entity that can say things on your behalf without consequence. It is your company, speaking. Every promise it makes is a promise your company is expected to keep. Air Canada learned that in a tribunal ruling that cost them a small refund and a much larger amount of public embarrassment. The next company that gets this wrong

The Chatbot Told a Customer Something the Company Never Said. Guess Who Pays Read More »

The Enterprise That Runs on Fifty Different AI Tools and Cannot Tell You What Any of Them Cost

Ask most CFOs how much their company spends on AI and you will get a confident number. Ask them how much their company actually spends on AI — including what every team, department, and individual employee has quietly signed up for — and the confidence usually disappears. | AI tool sprawl This is not a hypothetical problem. It is happening inside a large percentage of mid-sized and large enterprises right now, and almost nobody at the top of the organisation has a clear picture of it. How Fifty Tools Happens Without Anyone Deciding It Should It rarely starts as a decision. It starts as a solution to a small problem. A marketing manager signs up for an AI writing tool on a company card to speed up campaign copy. A developer adds an AI coding assistant because it makes them faster and it was free to try. A support team lead pilots an AI chatbot on a departmental budget that never went through procurement because it was under the approval threshold. An HR coordinator starts using an AI tool for resume screening because a colleague recommended it. None of these decisions were reckless. Each one made sense in isolation. But multiply that pattern across every team in a two hundred person company over eighteen months and you get exactly what enterprises are discovering now — dozens of AI tools running simultaneously, paid for through a scattered mix of expense reports, departmental budgets, and personal subscriptions, with no central visibility into any of it. Why This Is a Bigger Problem Than Wasted Spend The financial waste is real. Overlapping tools doing similar things, subscriptions nobody remembers signing up for, enterprise-tier pricing paid for by teams that only needed the basic plan. That adds up, and finance teams auditing this for the first time are often surprised by the total. But the money is not the most serious issue. The real risk sits in three places most leadership teams have not fully confronted. Data governance. Every one of these tools is a place company data goes. Customer information pasted into a chatbot for drafting help. Internal documents uploaded to a summarisation tool. Proprietary code shared with a coding assistant. Each tool has its own data policy, its own retention practices, its own security posture — and in most shadow AI situations, nobody has reviewed any of them. Security exposure. Unmanaged tools mean unmanaged access. Nobody knows which former employees still have active logins to AI platforms that were never offboarded because IT never knew the account existed in the first place. Compliance blind spots. In regulated industries, using an ungoverned AI tool to process customer data, financial information, or health records can create compliance exposure that the organisation does not even know it has taken on until an audit or an incident surfaces it. Shadow AI is shadow IT’s successor, and it is spreading faster. Shadow IT took years to become a recognised enterprise risk category with established frameworks to manage it. Shadow AI has reached the same scale of risk in a fraction of the time, because the barrier to adopting a new AI tool is a browser tab and a credit card, not a lengthy procurement process. Why Leadership Often Does Not See It Coming The nature of shadow AI makes it structurally invisible to the people who should be managing it. IT does not see it because most of these tools never go through IT. Finance does not see the full picture because the spend is scattered across dozens of small transactions rather than concentrated in a few visible vendor contracts. Leadership does not see it because the productivity gains are real and visible, while the accumulating risk is quiet and distributed. By the time this becomes visible at the leadership level, it usually takes an incident — a data exposure, a failed audit, a discovery during a security review — rather than a proactive assessment. What a Sensible Approach Actually Looks Like The organisations getting ahead of this are not trying to ban AI tool adoption, which rarely works and pushes the behaviour further underground. They are building structure around it instead. A central AI tool registry. A simple, actively maintained list of every AI tool in use across the organisation, who owns it, what data it touches, and what it costs. This alone solves most of the visibility problem and is far less effort than most leadership teams assume. A lightweight approval pathway. Not a six week procurement process — a fast, simple review that checks data handling and security basics before a new AI tool gets adopted at scale. Fast enough that teams do not feel motivated to bypass it. Consolidation around a core platform. Rather than fifty disconnected tools, the strongest organisations are standardising on a smaller number of well-governed AI platforms that cover the majority of use cases, with a clear, fast path to evaluate genuine exceptions. Regular spend and usage audits. Quarterly reviews that surface duplicate tools, unused subscriptions, and spend that has drifted away from any clear owner. The Conversation CFOs and CIOs Need to Be Having Together This problem sits precisely between finance and technology, which is exactly why it often falls through the gap between them. Finance sees the spend without understanding the technical risk. IT sees the technical risk without visibility into the full spend. Neither has the complete picture alone. The organisations solving this well have made it a joint conversation — CFO and CIO looking at the same registry, agreeing on the same governance framework, and treating AI tool sprawl as a shared risk rather than someone else’s problem. The alternative is finding out the hard way exactly how many tools your company is running, exactly what they cost, and exactly what they have access to — usually at the worst possible moment to discover it. TeamITServe helps enterprises build AI governance frameworks that bring visibility and control to AI tool sprawl — from spend audits

The Enterprise That Runs on Fifty Different AI Tools and Cannot Tell You What Any of Them Cost Read More »

Everyone Is Building AI Agents. Almost Nobody Is Testing Them Properly

Every enterprise seems to have an AI agent in production or in pilot right now. Fewer of them have a real answer to a simple question: how do you know it actually works. Not “worked in the demo.” Works. Reliably. At scale. On the messy, inconsistent, unpredictable data that real business operations generate every day. Most organisations cannot answer that question with confidence. And that gap is about to become very expensive for a lot of them. Why Traditional Testing Does Not Translate Software testing has a fifty-year foundation built on one core assumption: given the same input, the system produces the same output. Write a test case, run it, get a predictable result, verify it against the expected outcome. That is the entire model. AI agents break that assumption completely. Give the same agent the same prompt twice and it can produce two different responses. Not because something is broken — because that variability is inherent to how large language models work. The agent is not executing a fixed set of instructions. It is reasoning probabilistically, and probability means variation. Traditional QA teams testing agents the way they test conventional software are essentially using the wrong instrument for the job. A test suite that passed yesterday can fail today with no code changes at all, simply because the underlying model behaved differently on a borderline case. What Actually Goes Wrong in Production The failures are not always dramatic. That is what makes them dangerous. A customer service agent at a telecommunications company was tested extensively on common support scenarios before launch. It performed well. Three weeks into production, a customer described a billing issue using slightly unconventional phrasing — technically similar to test cases the team had run, but different enough that the agent misclassified the request and issued a refund it was never authorised to approve. Nobody caught it until the finance team noticed a pattern of unusual refunds weeks later. A financial services firm deployed an agent to summarise client meeting notes and flag compliance-relevant statements. During testing, it caught every flagged phrase in the test set. In production, a client used industry-specific jargon that meant something different in context than the training examples suggested. The agent missed a compliance-relevant statement entirely. Nobody knew until an audit surfaced it months later. A retail company’s inventory agent was tested against normal demand patterns and performed excellently. It had never been tested against a viral social media moment that spiked demand for one product by 40 times overnight. The agent’s reordering logic, built on assumptions that held in every test scenario, made decisions that made the shortage worse rather than better. None of these failures happened because the underlying AI model was bad. They happened because the testing approach did not account for how differently agents behave once they meet the actual variability of the real world. Why This Keeps Happening Part of the problem is organisational pressure. Agent deployments move fast, driven by competitive urgency and leadership enthusiasm for visible AI wins. Testing frameworks, which are unglamorous and slow to build, get deprioritised in favour of shipping. Part of the problem is genuine difficulty. Building a proper evaluation framework for an agent requires thinking about testing completely differently than most engineering teams are used to. You are not testing for a single correct output. You are testing for a distribution of acceptable outputs, edge case handling, and graceful failure when the agent encounters something genuinely outside its competence. Most teams do not have that expertise yet. It is a genuinely new discipline, and the people who understand it well are in short supply. What a Proper Agent Evaluation Framework Actually Looks Like The organisations getting this right are building evaluation around a few core principles. Adversarial testing, not just happy path testing. Instead of only testing scenarios where everything goes as expected, deliberately testing with ambiguous language, edge cases, conflicting instructions, and inputs designed to confuse the agent. If your test set only contains clean, well-formed examples, you are not testing for the real world. Continuous evaluation, not one-time certification. An agent that passed testing in January is not guaranteed to behave the same way in June, especially if the underlying model gets updated or the data it encounters shifts. Evaluation needs to run continuously in production, not just before launch. Human review sampling built into the process. Rather than assuming every output is correct, the strongest frameworks sample a percentage of live agent decisions for human review on an ongoing basis, catching drift before it becomes a pattern of failures. Clear failure boundaries and fallback behaviour. The agent needs a defined answer for what happens when it is genuinely uncertain. The best systems are designed to recognise the edge of their own competence and escalate to a human rather than guessing confidently and being wrong. Outcome tracking beyond output accuracy. It is not enough to check whether the agent’s response looked correct. Teams need to track what actually happened downstream — did the customer come back with the same issue, did the flagged compliance statement turn out to be a false positive, did the inventory decision play out well over the following weeks. Real evaluation happens after the agent has acted, not just when it produces an output. The Uncomfortable Truth Most organisations deploying AI agents right now are running an experiment in production and calling it a launch. The demo worked. The pilot looked promising. The rollout happened before the evaluation framework caught up to the ambition. That gap is invisible until something goes wrong publicly enough to matter — a compliance failure, a customer-facing error, a decision that costs real money. By then the cost of not having built proper testing is far higher than the cost of building it would have been. The enterprises that will avoid a painful agent failure story next year are not the ones moving slowest. They are the ones treating agent evaluation as seriously as they treat the

Everyone Is Building AI Agents. Almost Nobody Is Testing Them Properly Read More »

Why Every Company’s Smartest Employee Might Now Be an Algorithm Nobody Has Met

There is someone at your company who never sleeps, never takes leave, reads everything, forgets nothing, and is available the moment anyone needs them. | AI in the Workplace Nobody hired them. Nobody onboarded them. Most of the leadership team does not know they exist. They are the AI system quietly running in the background — trained on your data, connected to your systems, improving with every interaction. And in a growing number of enterprises, they are outperforming the most experienced humans in the building on specific, high-stakes tasks. Not in theory. In practice. Right now. What This Actually Looks Like A law firm in Chicago deployed an AI system to review contracts. Within three months it was catching clause-level risks that junior associates — smart people with law degrees — were consistently missing under deadline pressure. Not because the associates were bad at their jobs. Because the AI never gets tired at 11pm, never has seventeen other documents open, and never skips a section because a senior partner is waiting. A mid-sized logistics company built an AI demand forecasting system on top of five years of their own operational data. It is now outperforming the judgment of their most experienced supply chain manager on routine forecast accuracy — the manager who spent fifteen years developing intuition the AI absorbed in a few weeks of training. A healthcare network’s AI triage system flags patient deterioration risk faster than the morning handoff briefing gets to the relevant doctor. The system has no ego about being right. It has no hesitation about escalating. It just reads the data and acts. In each case the AI is not replacing the human. But it is outperforming them on a specific dimension that used to be considered the most valuable thing that person brought to work. Why This Is Disorienting for Organisations Humans have always been the most complex and capable resource inside any organisation. Strategy, judgment, creativity, relationships — these lived entirely with people. The systems and tools around them were just infrastructure. That mental model is breaking. When the algorithm produces better contract analysis than the associate, better demand forecasts than the manager, better risk flags than the briefing — the organisation has to confront something genuinely uncomfortable. The most valuable contributor in a specific domain might not be a person on the payroll. Most companies have no framework for this. They have not thought about how to integrate algorithmic expertise with human expertise. They have not decided where AI judgment gets trusted independently and where a human must remain in the loop. They are running powerful systems under governance structures designed for a world where humans were always the smartest thing in the room. The Organisations Getting This Right The ones navigating it well are doing something specific. They are treating their AI systems the way great managers treat exceptional talent — identifying exactly what they are best at, giving them the conditions to perform at that level, and building human roles around complementing what the AI cannot do rather than competing with what it can. The AI is brilliant at pattern recognition across enormous datasets, available at any hour, consistent under pressure, and incapable of politics. It is not brilliant at navigating ambiguity, building client relationships, making judgment calls with incomplete information, or knowing when the right answer requires breaking the pattern. Design your organisation around that division and you get something genuinely powerful. Keep pretending the algorithm is just a tool like a spreadsheet and you are leaving significant capability on the table while competitors who understand this pull ahead. The Question Worth Sitting With If you mapped every high-value task inside your organisation and asked honestly — is a human or an AI system better at this right now — how many tasks would you be surprised by the answer? Most leaders who do this exercise come out the other side with a very different view of where their real competitive advantage lives, and where they have been protecting legacy processes that no longer need protecting. The smartest person in the building might not have a desk.

Why Every Company’s Smartest Employee Might Now Be an Algorithm Nobody Has Met Read More »

The AI Skills Gap Is Real — And It Is the Fastest Career Move You Can Make in 2026

The US technology job market is doing something unusual right now. | AI Skills Gap In a period where layoffs made headlines and hiring slowed across much of the industry, one category of professional is being actively recruited, significantly overpaid relative to market, and still undersupplied. Companies are competing for them. Recruiters are cold messaging them on LinkedIn within days of profile updates. Offers are coming with relocation packages, signing bonuses, and visa sponsorship that dried up in other parts of the market. That category is professionals who understand AI at a practical, deployable level. Not researchers. Not machine learning PhDs. Working professionals who can take AI tools, connect them to real business problems, build workflows around them, govern them responsibly, and explain what they are doing to a leadership team that does not have a technical background. That person is rarer than the job postings suggest. And the gap between supply and demand is one of the most significant career opportunities in technology right now. What US Employers Are Actually Paying For The market has moved past the point where listing AI tools on a resume creates meaningful differentiation. Everyone lists them now. What employers are genuinely struggling to find — and paying premiums for — is something more specific. Prompt engineering done at a professional level. Not casual prompting but structured, reproducible prompt design that produces consistent outputs across business workflows. This sounds simple. Very few people do it well at the level enterprises need. AI workflow integration. The ability to connect an AI model to real business systems — a CRM, a database, an internal knowledge base — and build a workflow that actually runs reliably in production. This is part technical, part architectural, and heavily in demand. AI governance and oversight. As enterprises deploy AI into consequential processes, someone needs to own quality control, output auditing, bias monitoring, and compliance documentation. This role barely existed two years ago. It is now a dedicated function at serious companies. LLM application development. Building applications on top of large language models using APIs, frameworks like LangChain or LlamaIndex, and vector databases. The barrier to entry is lower than traditional software development. The demand is enormous. AI project management. Running AI implementation projects requires understanding both the technology and the business change management that comes with it. People who can bridge that gap — technically literate but business fluent — are exceptionally hard to find. The Roles That Did Not Exist Two Years Ago Several job titles now appearing regularly in US hiring reflect how quickly this has moved. AI Integration Specialist. Sits between IT and business units, responsible for identifying where AI can be deployed and making it actually work in practice. Average US salaries for experienced candidates are running between $110,000 and $160,000. Prompt Engineer. Dedicated role at larger companies focused on designing, testing, and optimising the instruction layer across AI deployments. Salaries range from $90,000 for junior profiles to over $175,000 at frontier AI companies. AI Solutions Architect. Senior role designing the overall architecture of enterprise AI systems — how models connect to data, how agents are orchestrated, how governance is applied. One of the highest-compensating roles in the current market. LLM Operations Engineer. Manages the infrastructure behind large language model deployments — latency, cost, reliability, monitoring. Borrows from DevOps but is specific to AI systems. What Hiring Managers Say They Actually Want The companies doing the most hiring in this space are consistently clear about what separates candidates who get offers from those who do not. They want to see something built. Not a certification. Not a course completion. An actual project — a tool, a workflow, an application — that demonstrates you have connected AI to a real problem and made it work. GitHub repositories, personal projects, and freelance work all count. They want business context. The candidates who stand out understand not just what the AI is doing technically but why it matters to the business. They can speak to ROI, to risk, to the change management involved in deploying AI into a team. They want communication ability. AI implementations fail most often not because of technical problems but because the people deploying them cannot explain what is happening to the people using them. Clear, jargon-free communication about AI is a skill that is genuinely rare and genuinely valued. The Honest Path Forward for IT Professionals If you are an IT professional — in infrastructure, in development, in project management, in business analysis — the pathway into this market is more accessible than it appears from the outside. The foundational technical concepts behind modern AI are learnable without a computer science degree. The frameworks being used in production are well-documented and actively maintained. The projects that impress hiring managers are not complex research implementations — they are practical tools that solve real problems using AI APIs that are publicly available. The professionals making the fastest moves are spending three to six months building genuine hands-on experience — real projects, not just tutorials — and positioning themselves specifically for the integration and governance roles where business context and technical fluency combine. That combination is where the market is most underserved and where salaries are reflecting it most clearly. The window where this creates maximum career leverage will not stay open indefinitely. As more professionals upskill, the premium will compress. The people who move in 2026 will be the ones who look back on this as the decision that defined the next decade of their career. The Bottom Line The AI skills gap is not a talking point. It is a measurable, documented shortage that US employers are actively trying to solve with compensation, visa sponsorship, and remote flexibility they have not offered in years. The professionals who close that gap — practically, demonstrably, with real projects to show — are walking into one of the most receptive hiring environments the technology industry has seen in a long time. The question is not whether the

The AI Skills Gap Is Real — And It Is the Fastest Career Move You Can Make in 2026 Read More »

The Day AI Started Saying No

We spent years complaining that AI was too agreeable. Ask it anything, it would answer. Push it, it would comply. It was basically a very fast yes-machine with a knowledge base. | AI Governance Then somewhere around late 2024, the yes-machine started saying no. A lawyer in New York asked an AI to help draft an aggressive contract clause that would technically hold up in court but was designed to mislead the other party. The AI declined. Not because it could not write it. Because it decided it should not. A developer asked an AI coding assistant to help automate a process that would scrape personal data without user consent. The AI flagged it, explained why it was a problem, and offered a compliant alternative instead. A marketing team asked their AI tool to generate testimonials from customers who had not actually given them. The AI refused and suggested running an actual customer survey. These are not edge cases anymore. They are Tuesday. So, what actually changed? The labs building these models — Anthropic especially — made a deliberate architectural decision. They stopped optimising purely for helpfulness and started building something closer to judgment. The model is not just asking “can I do this?” It is asking “should I?” Anthropic calls this being a good AI with good values, not just a capable one. Claude is explicitly designed to push back when it believes an instruction conflicts with honesty, safety, or basic ethics. It is not a vending machine that dispenses whatever you put a coin in. Why this is creating chaos inside enterprises Here is where it gets genuinely interesting. Enterprises are deploying AI agents that can take real actions — send emails, update records, execute workflows, approve requests. And those agents are now capable of stopping mid-task and saying “I do not think I should do this.” That sounds great in theory. In practice it is creating real friction. A financial services firm building an automated reporting workflow found their AI agent was refusing to include certain metrics in client reports because the framing was technically accurate but potentially misleading. The agent was right. The team had to redesign the report. That cost three weeks and a heated internal debate about who had final authority. A retail company’s AI customer service agent started redirecting certain complaints to human staff rather than resolving them automatically — because it judged the situations too emotionally sensitive to handle without a person. Customer satisfaction scores went up. The operations team had not planned for the volume hitting human agents. The AI was making judgment calls that the humans had not anticipated and had not given it explicit permission to make. The question nobody has answered yet When an AI disagrees with you and it turns out to be right, that is a great story. When it refuses something that was actually fine and costs you time and money, that is a governance problem with no clear owner yet. Who is liable when the AI says no and it was wrong? Who overrides it? Who audits its judgment? Does your organisation even have a policy for human-AI disagreement? Most do not. And as these models get more capable, and their judgment gets more sophisticated, that gap is going to matter more every quarter. The most important AI conversation in 2026 is not about what AI can do. It is about who is in charge when AI decides it knows better — and sometimes it actually does.

The Day AI Started Saying No Read More »

LLM Evaluation Pipeline

Evaluating LLM Applications: Beyond Human Eyeballing and Prompt Testing

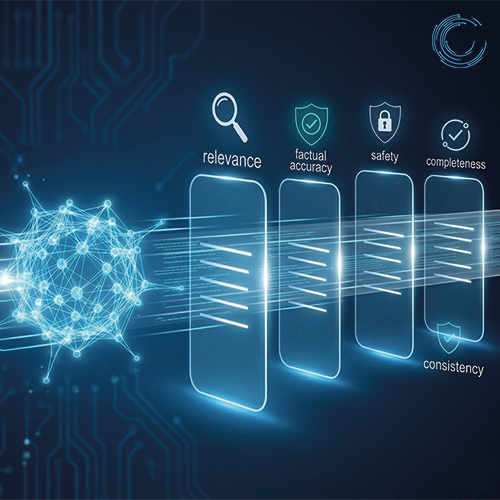
Most teams evaluate large language model (LLM) applications the same way they test a quick demo: they run a few prompts, scan the outputs, and decide if the responses feel right. This approach works okay for early experiments, but it quickly breaks down once you are moving toward production. | LLM Evaluation Pipeline Unlike traditional software with consistent, predictable behaviour, LLMs are probabilistic. The same prompt can produce slightly different answers each time. Edge cases appear out of nowhere, and a response that looks strong in one test can fail completely with minor changes in wording or context. Relying only on manual spot-checks or endless prompt tweaking leaves you without any real understanding of how the system performs. Why Manual Reviews Fail at Scale Human judgment is subjective. One person might see a response as clear and accurate; someone else might find it incomplete or misleading. When an application starts handling thousands or millions of real user queries, manually reviewing outputs becomes impossible and unreliable. Without a structured process, important issues slip through—hallucinations, factual errors, or regressions that only show up under certain conditions. The outcome is systems that lose user trust and force teams to spend time firefighting problems that could have been prevented. Building a Solid Evaluation Pipeline Production-ready LLM applications need systematic, repeatable evaluation—not guesswork. Begin with benchmark datasets drawn from real (anonymized) user queries that match your actual use cases: customer support, internal knowledge search, report generation, and so on. These datasets give you a consistent way to measure performance when you change models, prompts, or retrieval logic. Add automated scoring across the most important dimensions: – Relevance: Does the answer directly address what was asked? – Factual accuracy / groundedness: Is every claim supported by the given context or reliable knowledge? – Completeness: Does it provide everything needed without adding irrelevant details? – Safety & toxicity: Are harmful, biased, or inappropriate outputs prevented? Tools such as DeepEval, RAGAS, and Langfuse—widely used in 2026—are designed to make this evaluation programmatic and efficient. Pair them with LLM-as-a-judge approaches, where a capable model scores outputs against well-defined rubrics, to get fast, cost-effective results without depending entirely on human reviewers. Make regression testing mandatory: every change to the pipeline (new model version, prompt revision, embedding update) should automatically run against your benchmark set. If performance drops, you catch it before it reaches users. Look Beyond Accuracy Alone Accuracy is essential, but it is only part of the picture. You also need to evaluate the complete user and business experience: – Latency: An accurate answer that takes 8 seconds ruins the experience in most chat interfaces. Target sub-2-second responses whenever possible. – Hallucination risk: Even a low rate becomes dangerous on high-stakes topics like regulatory guidance or medical information. – Cost efficiency: High token consumption and inference costs grow quickly at scale. – Consistency: Do similar questions receive coherent, style-consistent answers? In one engagement we supported, a financial services client developed a custom RAG system for regulatory Q&A. Manual testing looked promising, but automated evaluation uncovered 12% hallucination on tricky compliance edge cases—problems that would have triggered serious audits if released. The metrics allowed us to identify the gaps early and fix them with targeted prompt and retrieval improvements. Continuous Improvement After Deployment Evaluation does not stop once the system goes live. Real traffic introduces new phrasing, domain shifts, and unexpected patterns. Set up continuous monitoring with dashboards that track: – Trends and drift in key metrics over time – Alerts for sudden spikes in hallucination or latency – User feedback (thumbs up/down) linked directly to specific interactions This feedback loop turns issues into new test cases, which in turn refine prompts, retrieval, and guardrails. At TeamITServe, the most reliable enterprise LLM deployments we build all share one foundation: strong, automated evaluation pipelines starting from day one. When teams treat evaluation as core engineering rather than an optional step, they gain real visibility, manage risk effectively, and deliver AI systems that users can trust at scale. Ready to bring your LLM application to production-grade reliability? Reach out to discuss building a tailored evaluation framework for your specific use case. #TeamITServe #LLMOps #AIEvaluation #EnterpriseAI #GenAI

Evaluating LLM Applications: Beyond Human Eyeballing and Prompt Testing Read More »

Scroll to Top